Overall structure. The model composed of a Visual Encoder, a ...
Kitchens4,222 ideas

Bathrooms2,442 ideas
Kids Rooms1,868 ideas
Bedrooms1,657 ideas
Powder Rooms1,638 ideas
Family Rooms1,414 ideas
Dining Rooms1,403 ideas
Laundry1,361 ideas
Basements1,338 ideas
Entries1,286 ideas
Home Bars1,168 ideas
Hallways1,131 ideas
Home Offices1,098 ideas
Living Rooms1,038 ideas
Nurseries923 ideas
Closets & Storage922 ideas
Sunrooms851 ideas
Decks792 ideas
“Visual Encoder/Decoder Model”
0 in catalog · +119 from web
More from the web

Vision–Language Model for Visual Question Answering in Medical Imagery

Overall structure. The model composed of a Visual Encoder, a ...

Proposed visual encoding model. (A) Model framework. A visual ...

Video Transformer(VIT): A Deep Learning Model for Video Processing | by ...

What Are Visual Language models (VLMs) And How Do They Work? - TopDailyBlog

Encoder-decoder architecture used for transforming visual spectrum to ...

Visual Encoding

Visual Encoding

Stateful Visual Encoders for Vision-Language Models | AI Research Paper ...

May I see what you see? Predicting visual features from neuronal ...

Teach ML models to generalize information from visual images and ...

[2406.09167] Vision Transformer Segmentation for Visual Bird Sound ...

Encoder-decoder architecture used for transforming visual spectrum to ...

Encoder-Decoder model architecture for training. | Download Scientific ...

Open AI introduces Sora: A Next-Gen Text-to-Video AI Model

VideoPrism: A Foundational Visual Encoder for Video Understanding

VisionLLM: Large Language Model is also an Open-Ended Decoder for ...

Steerable Visual Representations

Figure 1.1 from Vision Encoders in Visual Question Answering | Semantic ...

The Optimal Choice of the Encoder–Decoder Model Components for Image ...

Decoder Model _ Exploring Decoder-Only Transformers for NLP and More – WEOS

Enhancing Visual Image Captioning with SWIN Vision Transformers ...
Visual representation of the Encoder-Processor-Decoder model, Section ...

[2005.01400] Does Visual Self-Supervision Improve Learning of Speech ...

Encoder-decoder model structure. | Download Scientific Diagram

Overview of VT-CLIP where text encoder and visual encoder refers to the ...

[论文评述] Noise-Robust AV-ASR Using Visual Features Both in the Whisper ...

Masked autoencoder (MAE) for visual representation learning. Form the ...

Visual Encoding Example

Vision talks: Visual relationship-enhanced transformer for video-guided ...

Mastering Model Optimization: In-Depth Guide to Fine-Tuning and ...
Flow diagram of our model: V θ denotes the Visual Encoder, which ...

The model architecture employing an encoder-decoder structure. © 2020 ...

Encoder Decoder A Hierarchical Encoder Decoder Model For SPSS

[论文评述] One Layer Is Enough: Adapting Pretrained Visual Encoders for ...

Figure 2 from Using FCOS and an Encoder-Decoder Model to Detect and ...

What Is Encoder Decoder Model at Qiana Flowers blog

[Literature Review] Video Prediction Models as General Visual Encoders

Figure 1.1 from Vision Encoders in Visual Question Answering | Semantic ...

(PDF) High Visual Quality Image Steganography Based on Encoder-Decoder ...
Network architecture of the ViT-based visual encoder. | Download ...

What Is Encoder Decoder Model at Qiana Flowers blog

[論文レビュー] An Efficient and Effective Encoder Model for Vision and ...

Overview of encoder/decoder models in GNNs, algorithms and ...

Intro To The Encoder-Decoder Model And The Attention Mechanism – Bang Bus

How to Build a Generative AI Model for Image Synthesis? | Blog

Encoder-Decoder model combined with attention mechanism | Download ...

Vision Transformer Image Classification | MindSpore 2.0 Tutorials ...

Encoder Decoder Architecture Explained at Brenda Ashburn blog

[2311.16161] Vision Encoder-Decoder Models for AI Coaching

Vision Language Models (VLMs) Explained | DataCamp

大视觉模型要来了?Large Vision Models - 知乎

Best Computer Vision Models | Encord

The Illustrated Image Captioning using transformers - Ankur | NLP ...

Putting Encoder - Decoder Together - Scaler Topics

Paper Review: Unveiling Encoder-Free Vision-Language Models – Andrey ...

[2307.13721] Foundational Models Defining a New Era in Vision: A Survey ...

[2501.10071] CLIP-PCQA: Exploring Subjective-Aligned Vision-Language ...

Chapter 8, Machine Learning and Computer Vision – Vision Readings

Explain the Transformer Architecture (with Examples and Videos) - AIML.com

The overall architecture of our proposed approach, where the vision ...

Vision-Language Models: How They Work & Overcoming Key Challenges | Encord

Examples of the two vision-language understanding tasks. For VQA ...

[1909.11059] Unified Vision-Language Pre-Training for Image Captioning ...

A Comparative Evaluation of Transformer-Based Vision Encoder-Decoder ...

README.md · Qwen/Qwen2-VL-2B-Instruct at main

Vision-Language-Vision Auto-Encoder: Scalable Knowledge Distillation ...

Illustration of Vision Decoder. The vision decoder consists of a ...

Unveiling Encoder-Free Vision-Language Models | AI Research Paper Details

Vision Language Models là gì? Nguyên lý hoạt động, lợi ích và ứng dụng

Aman's AI Journal • Primers • Document Intelligence

GitHub - DragosUnguru/VisualStorytelling: My bachelor's thesis ...

Figure 2 from Bengali Image Captioning Using Vision Encoder-Decoder ...

Image Captioning using PyTorch and Transformers in Python - The Python Code

Advancements in Vision–Language Models for Remote Sensing: Datasets ...

Machine-vision based encoder-decoder convolutional neural networks ...

Dissecting the Vision Transformer (ViT): Architecture and Key Concepts ...

Vision Transformers: From Idea to Applications (Part Four)
GPT and other LLM’s: decoder only v/s encoder-decoder models? | by ...

Figure 1 from Bengali Image Captioning Using Vision Encoder-Decoder ...

Variational Autoencoder • VAE • AI Terminology - AI Blog

(PDF) Understanding the architecture of vision transformer and its ...

Encoders and Decoders in Generative AI | by Mansoor Basha Syed | Medium
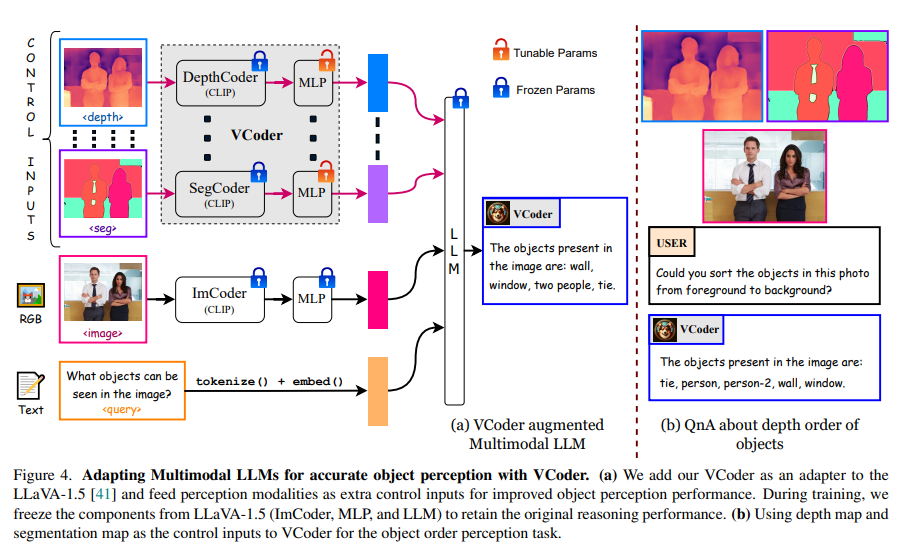
Researchers from Microsoft and Georgia Tech Introduce VCoder: Versatile ...

UNIT; Unifying Image and Text Recognition in One Vision Encoder - AAA ...

Encoding And Decoding

VCoder: Versatile Vision Encoders for Multimodal Large Language Models ...

Encoder Decoder Models - GeeksforGeeks

Introduction to LLMs: The RNN Encoder-Decoder Architecture

Medium

[2304.06286] Automated Cardiovascular Record Retrieval by Multimodal ...

AI learns how vision and sound are connected, without human ...

Paper Review: Unveiling Encoder-Free Vision-Language Models – Andrey ...

Resolving Knowledge Conflicts in Vision-Language Models

A Systematic Literature Review on Using the Encoder-Decoder Models for ...

Imitating Shortest Paths in Simulation Enables Effective Navigation and ...

InternVL: Scaling up Vision Foundation Models and Aligning for Generic ...

Attention mechanism based Encoder-Decoder framework. x i is a pixel or ...

Scrap Tf: Revolutionizing Data Extraction Through Smart Transformer ...

Hierarchical Pre-Training of Vision Encoders with Large Language Models

Generative AI Tech Stack: A Detailed Breakdown - Idea Usher

VLMT: Vision-Language Multimodal Transformer for Multimodal Multi-hop ...

Figure 1 from A Comparative Evaluation of Transformer-Based Vision ...

Available Encoders — Segmentation Models Documentation – DKUZS

Multi-Task Video Captioning with a Stepwise Multimodal Encoder

OneVision-Encoder A vision architecture that aligns with information ...

Retinal Lesion Segmentation Using Transfer Learning with an Encoder ...

What is AI what is LMM and why it is amazing for the IoT | Cloud Studio ...

EVEv2: Improved Baselines for Encoder-Free Vision-Language Models · HF ...
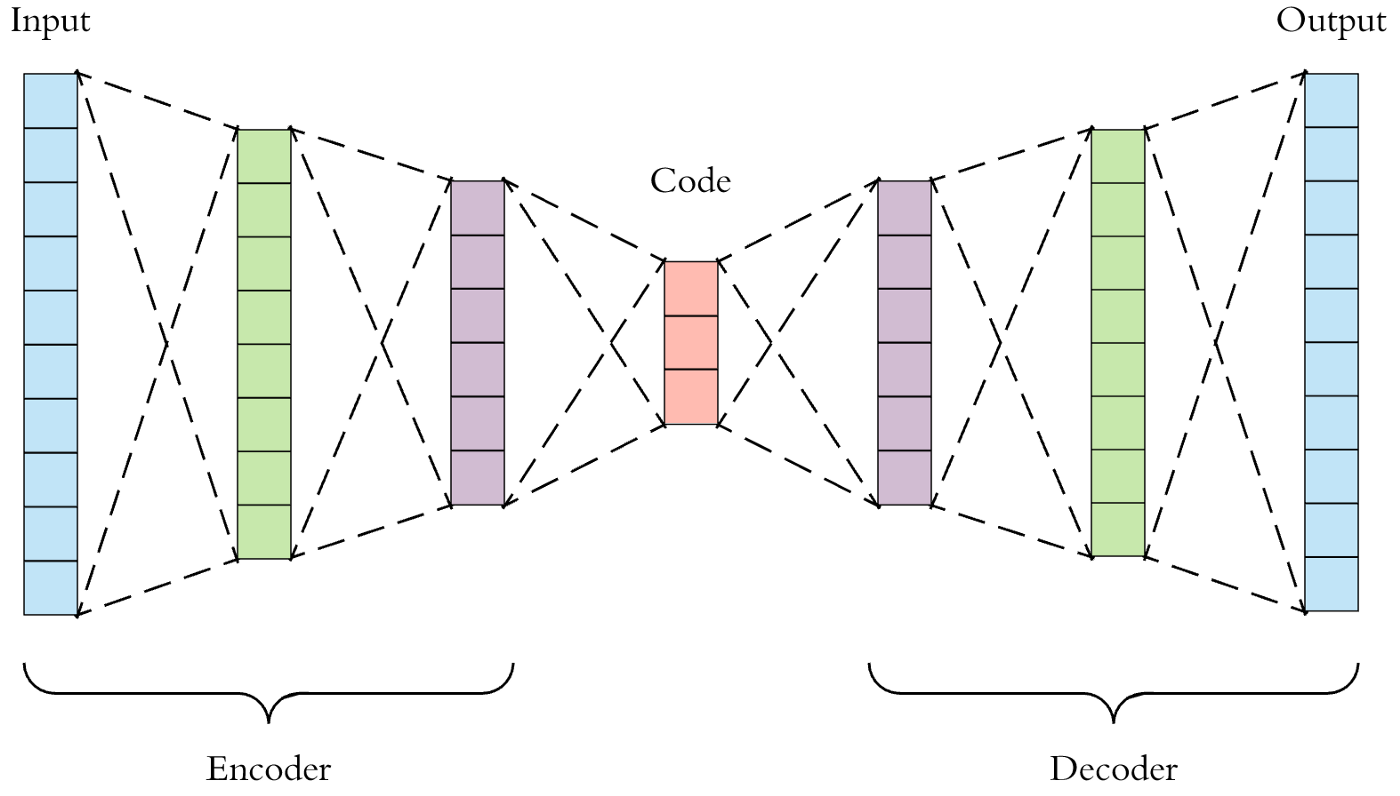
What is an Autoencoder?

Image Captioning Using Hugging Face Vision Encoder Decoder — A Step 2 ...

FIGURE Structure of encoder layer in Vision Transformer. | Download ...
A high-level transformer-based encoder-decoder network. | Download ...

Auto Tagging Videos with Vision-Language Models | AI Tutorial | Next ...

Vision-Language Models (VLMs): Bridging Vision and Language | PPTX

A Systematic Literature Review on Using the Encoder-Decoder Models for ...

The proposed Encoder-decoder framework with attention model. | Download ...

Demystifying Ai Models Encoders Decoders And Embeddings Omegatypes Of ...