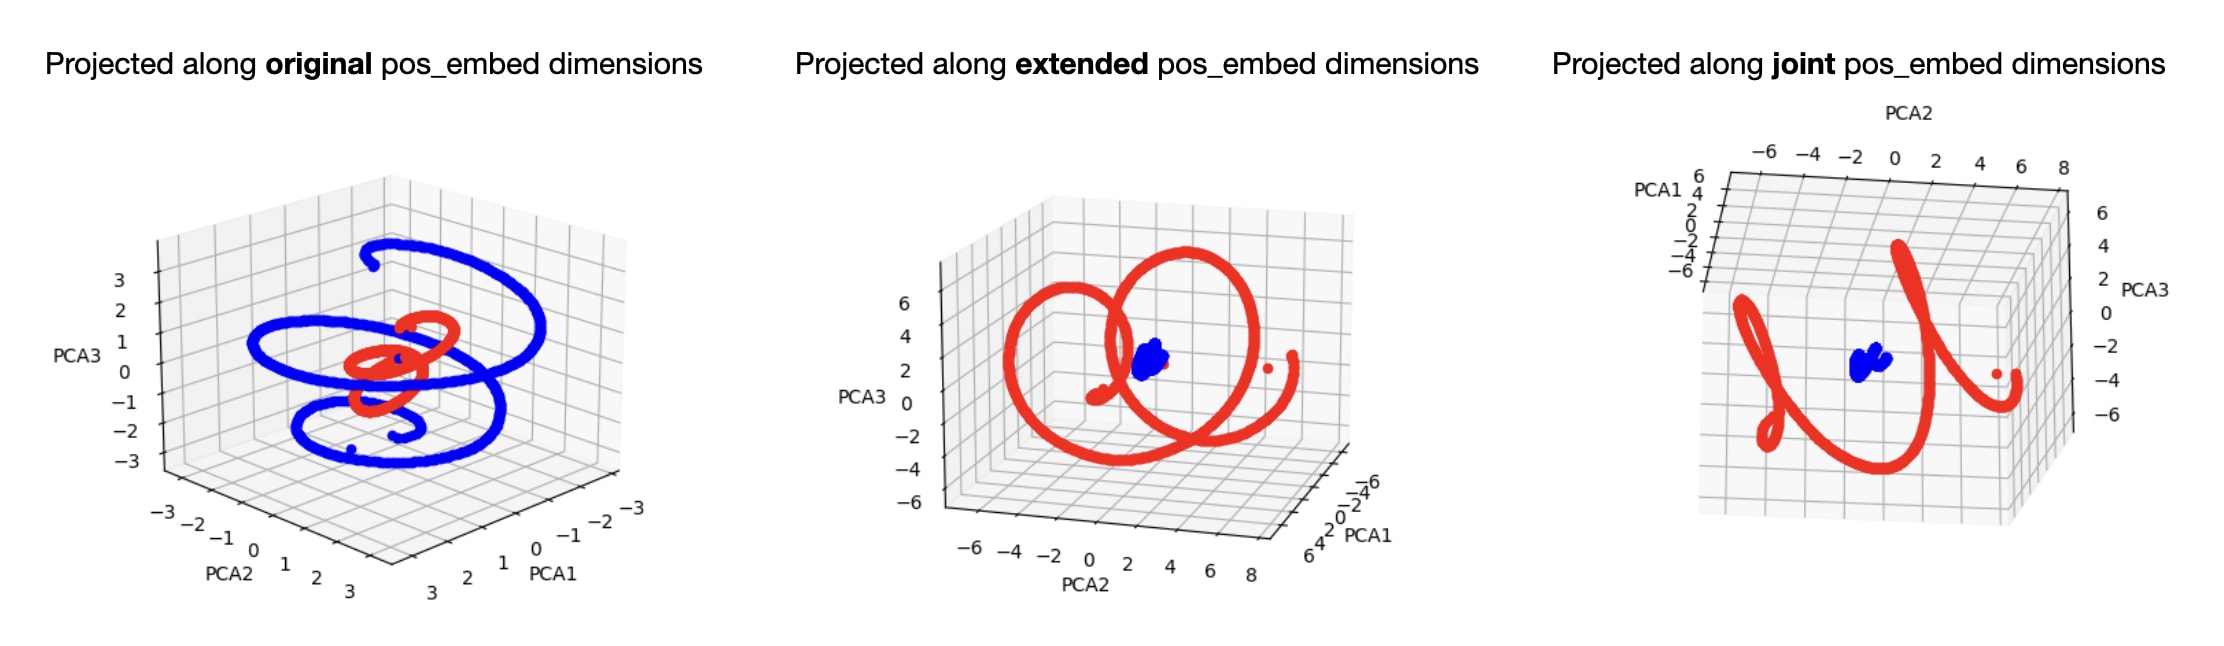
Token embedding v/s Segment Embedding v/s Position Embedding In the ...

Kitchens4,222 ideas

Bathrooms2,442 ideas

Kids Rooms1,868 ideas

Bedrooms1,657 ideas

Powder Rooms1,638 ideas

Family Rooms1,414 ideas

Dining Rooms1,403 ideas

Laundry1,361 ideas

Basements1,338 ideas

Entries1,286 ideas

Home Bars1,168 ideas

Hallways1,131 ideas

Home Offices1,098 ideas

Living Rooms1,038 ideas

Nurseries923 ideas

Closets & Storage922 ideas

Sunrooms851 ideas

Decks792 ideas
“Token Position Embedding”
0 in catalog · +120 from web
More from the web
![[LayoutLM] Different position embedding of the CLS token from the paper ...](https://user-images.githubusercontent.com/25688648/98592535-6ff37680-2304-11eb-82dc-9d156dd25917.png)
[LayoutLM] Different position embedding of the CLS token from the paper ...

Structure of AP-BERT model. Input Embedding includes four parts: token ...

LLM Basics: Embedding Spaces - Transformer Token Vectors Are Not Points ...

Detailed design of token embedding with attention. | Download ...

RoPE: A Detailed Guide to Rotary Position Embedding in Modern LLMs

LLM Basics: Embedding Spaces - Transformer Token Vectors Are Not Points ...

RoPE: A Detailed Guide to Rotary Position Embedding in Modern LLMs

Tutorial 04: Token Embedding & Positional Embedding | Build an LLM From ...

LLM Basics: Embedding Spaces - Transformer Token Vectors Are Not Points ...

LLM Basics: Embedding Spaces - Transformer Token Vectors Are Not Points ...
Demonstrates how each token undergoes independent embedding before ...

Four different approaches of global visual token embedding | Download ...

Schematic of convolutional token embedding | Download Scientific Diagram
![[2212.05262] Position Embedding Needs an Independent Layer Normalization](https://ar5iv.labs.arxiv.org/html/2212.05262/assets/x1.png)
[2212.05262] Position Embedding Needs an Independent Layer Normalization

RoPE: A Detailed Guide to Rotary Position Embedding in Modern LLMs

Architecture of the Embedding Layer During Training of LLMs - ML Digest

The Position Encoding In Transformers!

nlp - BERT - The purpose of summing token embedding, positional ...

Journey of a single token through the LLM Architecture

The representation of the dialogue input. The input embedding for each ...
How Tokenization & Embedding Actually Work
Mixed-token embedding method. | Download Scientific Diagram

The input representation of SMILES. The input is the sum of the token ...
Token embeddings for predicting gates and polygons. The first 2n ...

An exploration of GPT-2's embedding weights — LessWrong

Architecture of the Embedding Layer During Training of LLMs - ML Digest

Embedding 在大模型中起什么作用? | AI 学习资源站

The model architecture. The sum of the token embeddings, segment ...

Embedding

Mixed-token embedding method. | Download Scientific Diagram
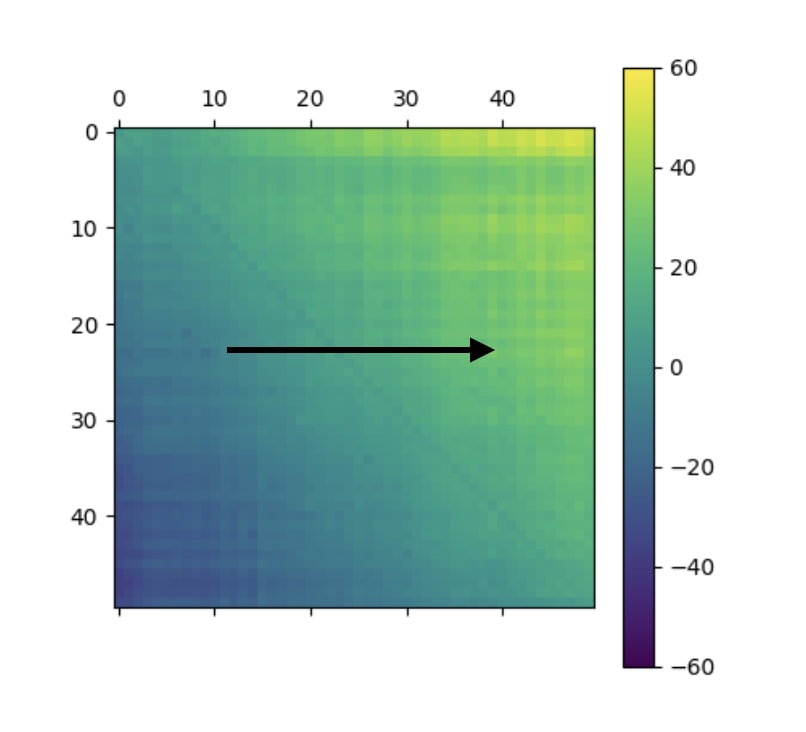
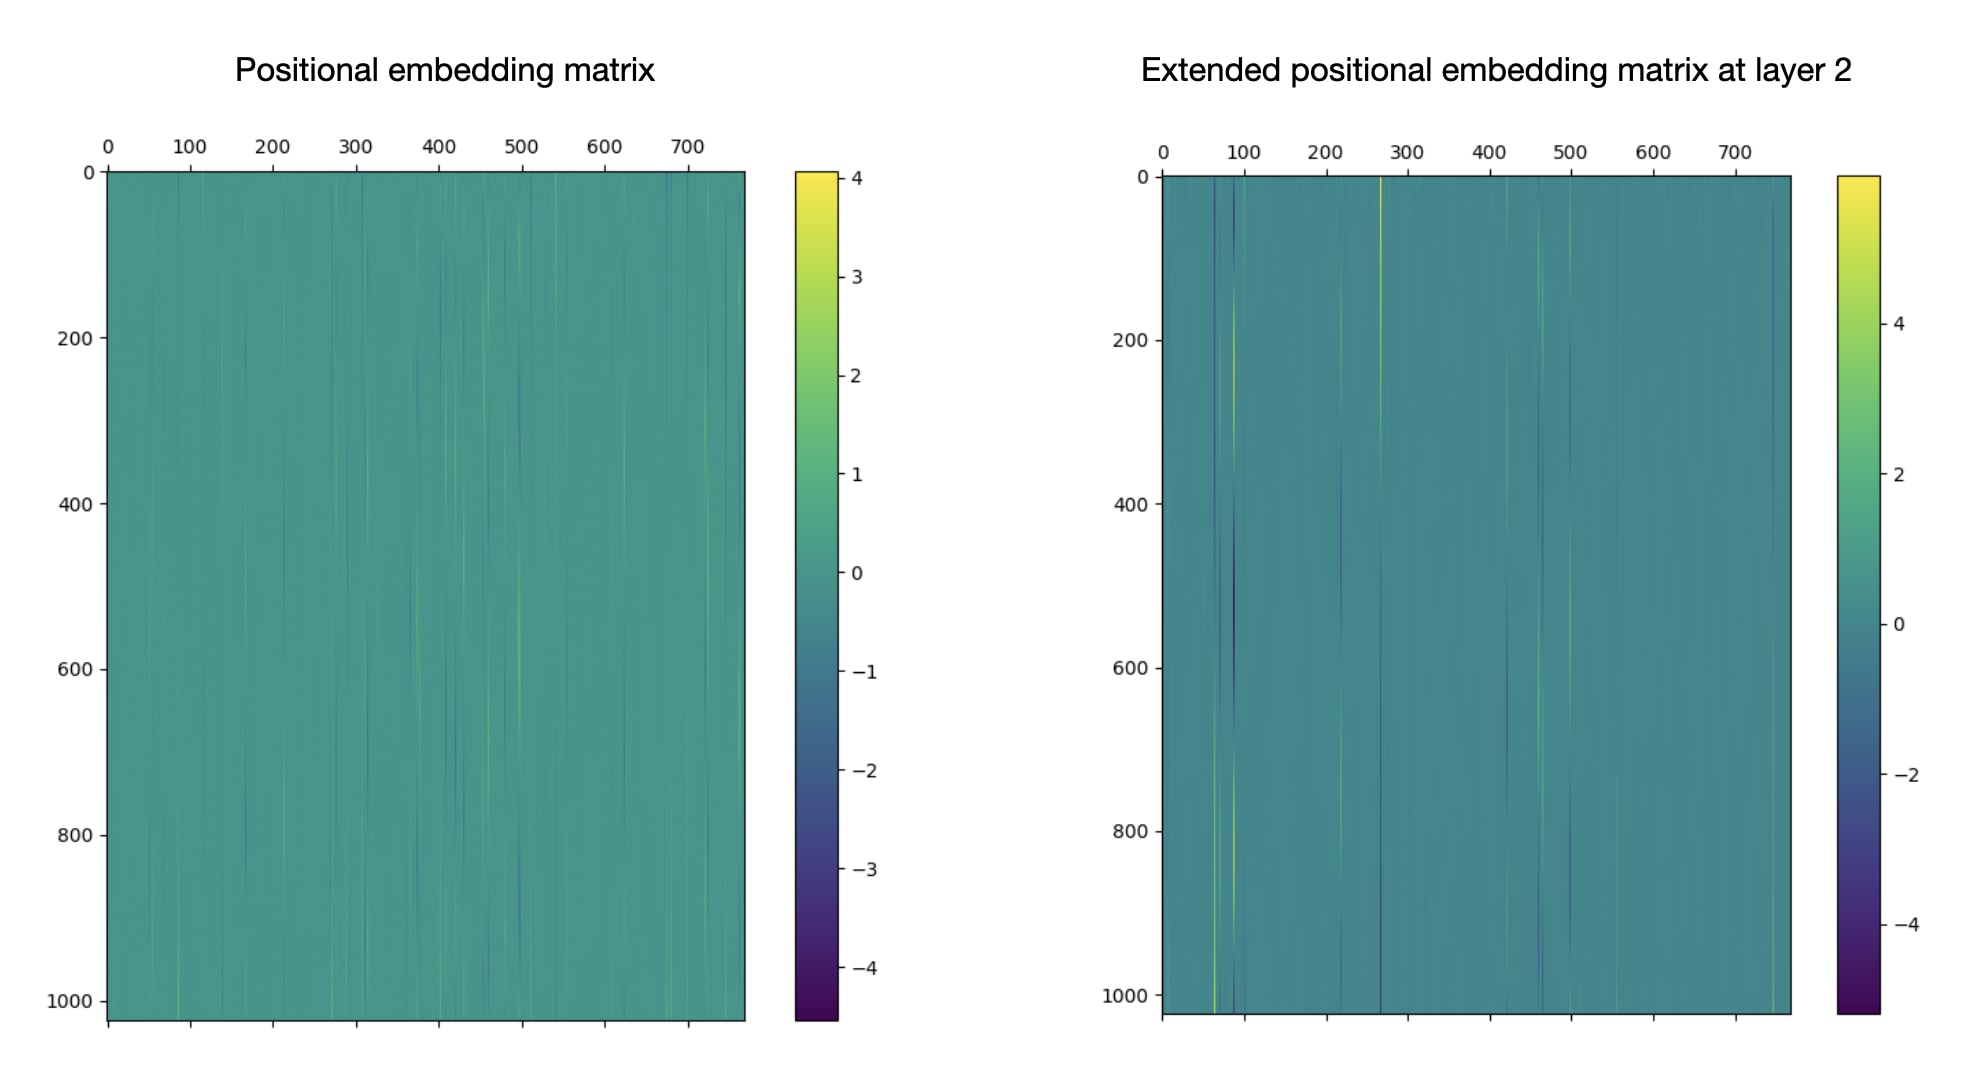
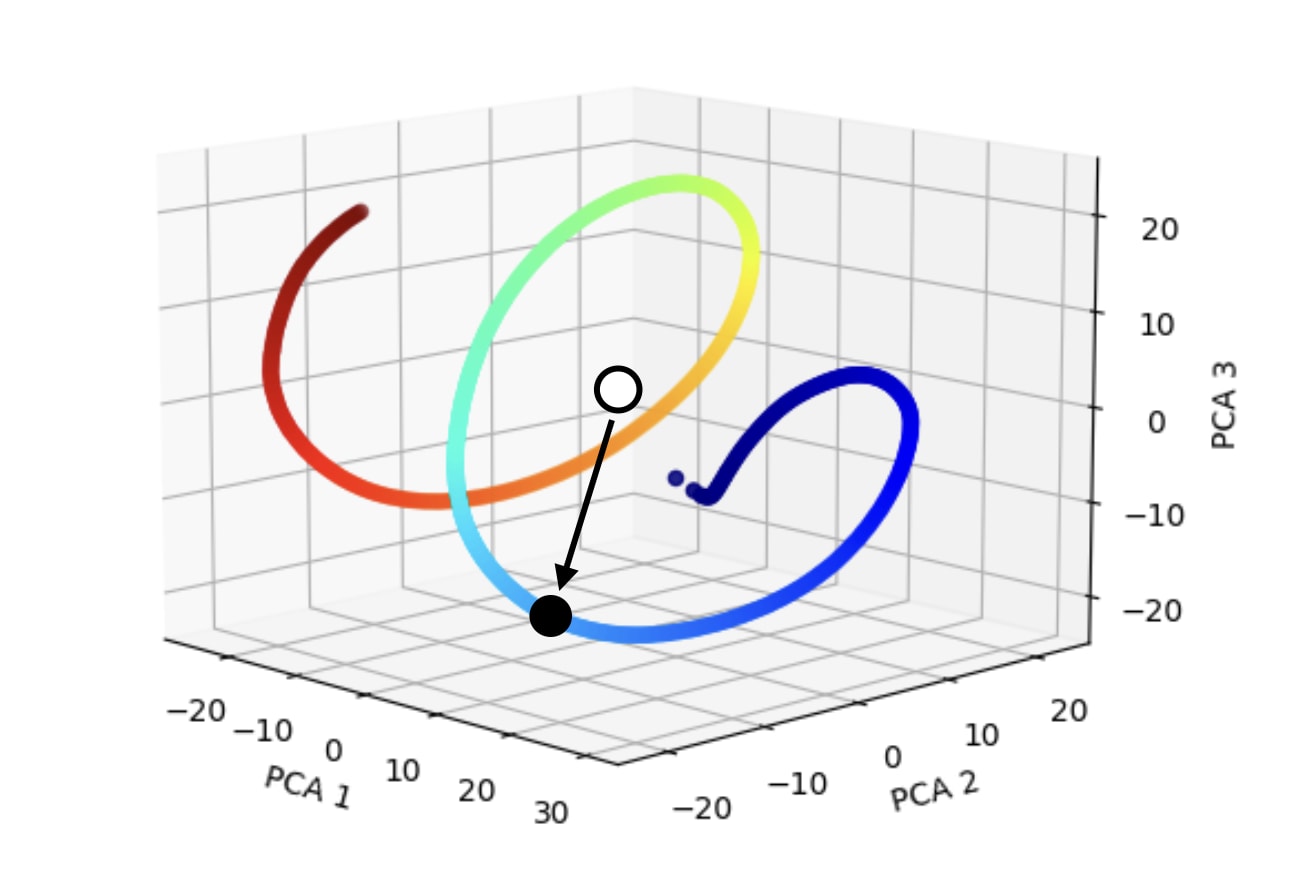
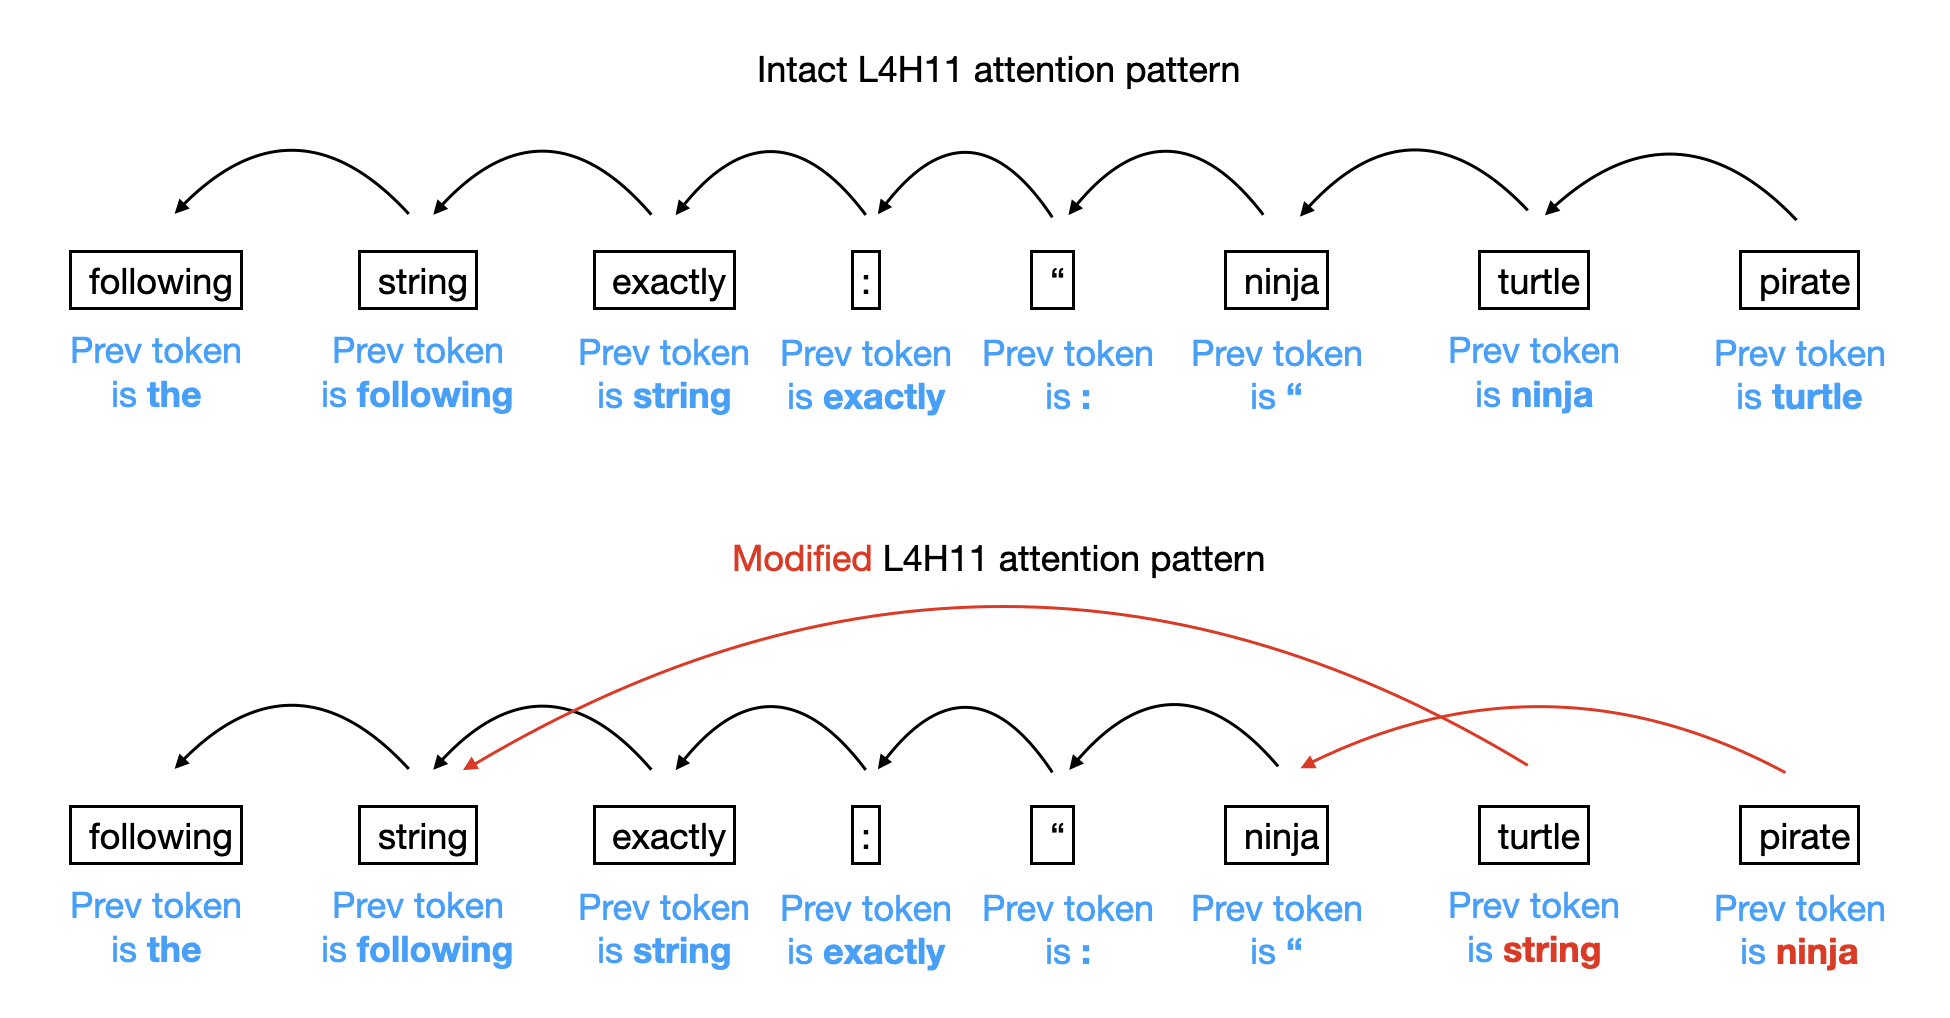
The positional embedding matrix and previous-token heads: how do they ...

Embedding #notebook_tokenizer 怎么生成 embedding向量-CSDN博客

Architecture of the Embedding Layer During Training of LLMs - ML Digest

Tokenization Embedding Explained | Restackio

Token Embedding详解:原理、代码实现与实战指南 | AwesomeML
The positional embedding matrix and previous-token heads: how do they ...

探秘Transformer系列之(7)--- embedding - 罗西的思考 - 博客园

An Introduction to Position Embeddings | by AIMuse | Medium
The positional embedding matrix and previous-token heads: how do they ...

Building my own language model: Embedding layers (Part 3) – Chris Menz ...

Tokenization vs Embedding - How are they Different? | Airbyte
![[动手写 bert 系列] bert embedding 源码解析,word_embedding/position_embedding ...](http://i0.hdslb.com/bfs/archive/1e0ccb06f981eefeadbb89136f0e3c068a05fb68.jpg)
[动手写 bert 系列] bert embedding 源码解析,word_embedding/position_embedding ...
Token Embeddings vs Positional Embeddings

Learned Positional Embedding — Why Self-Attention Needs Word Order ...

Token Embedding(词嵌入)和Positional Encoding(位置编码)的矩阵形状关系及转换过程-CSDN博客

Contextual Position Encoding (CoPE): A New Position Encoding Method ...

An exploration of GPT-2's embedding weights — LessWrong

English facts being passed as input to mT5's encoder with token ...

Embedding Layer vs Tokenizer. The Embedding layer and Tokenizer are ...
The positional embedding matrix and previous-token heads: how do they ...

How To Compute The Token Consumption Of Vision Transformers? » ML Digest

Late Interaction Retrieval with Dense Token Embeddings - Qdrant
The positional embedding matrix and previous-token heads: how do they ...

An Introduction to Position Embeddings | by AIMuse | Medium
The positional embedding matrix and previous-token heads: how do they ...

Using transformers - a drama in 512 tokens - Speaker Deck

从零开始实现大语言模型(三):Token Embedding与位置编码-CSDN博客

Implementing GPT Architecture Step-by-Step | AI Tutorial | Next Electronics

Understanding BERT | Embeddings
AI Series - Part 2: Tokens Embedding, Positional Encoding

Understanding Transformers, Step by Step

Giving the Model a Sense of Order - Positional Encoding

Medium

Language Model Training and Inference: From Concept to Code

Building a GPT from Scratch in JAX/Flax: | Brayan’s Blog

Positional Embeddings in Transformer Models: Evolution from Text to ...

【第四章:大模型(LLM)】05.LLM实战: 实现GPT2-(1)文本token到Embedding的代码实现_gpt-2 ...

Transformer Architecture Explained: Self-Attention, Encoders, and Decoders

Understanding Positional Embeddings in Transformers: From Absolute to ...

PyLessons

Transforming Text: The Rise of Sentence Transformers in NLP - Zilliz Learn

Generative AI Handbook Book Club – 14. Positional Encoding

machine learning - How are the TokenEmbeddings in BERT created? - Stack ...

MLIR Part 7 - Transformers

image by the author the result that we get with

2. Working with Text Data

7. Pre-training — GenAI: Best Practices 1.0 documentation

A Guide to Positional Embeddings: Absolute (APE) vs. Relative (RPE ...

Basics of Generative AI: Models, Tokenization, Embeddings, Text ...

从零开始实现大语言模型(三):Token Embedding与位置编码-CSDN博客

HFBRI-MAE: Handcrafted Feature Based Rotation-Invariant Masked ...

Understanding how LLM inference works with llama.cpp

Tokenization vs Embeddings: Key Differences Explained
ByteByteGo | Technical Interview Prep

Architectures — Deep Learning 101 for Audio-based MIR

Understanding BERT | Embeddings
File:Token embedding.png - statwiki

Transformers: Revolutionizing NLP with Self-Attention | PDF

LLMs From Scratch - Chapter 2: Dataloader Creation – Daniel Pickem

Positional encoding

Transformer原理简明讲解 | 我的学习笔记 | 土猛的员外

2. Data Preparation and Sampling | Tyan Blog

Understanding Multimodal LLMs - by Sebastian Raschka, PhD

code embedding研究系列一-基于token的embedding_token embedding-CSDN博客

Practical Prompt Engineering - by Cameron R. Wolfe, Ph.D.

Vision Transformer (ViT) Architecture - GeeksforGeeks

In The Loop | 当计算撞上内存墙:Attention!注意力机制及其优化算法浅析
Data Science Dojo added a new photo. - Data Science Dojo
Tokenization and Embeddings Explained | PDF | Algorithms | Artificial ...

What role does positional information play in a transformer-based LLM?

How LLMs Embeds Input Tokens? - by Nikita Prasad

Transformers
![[Hands-On] Build Tokenizer using BPE (Byte Pair Encoding) | by Hugman ...](https://miro.medium.com/v2/resize:fit:1358/1*ECAVNGlzLHZ31SEFq8qHqw.png)
[Hands-On] Build Tokenizer using BPE (Byte Pair Encoding) | by Hugman ...

Attention Is All You Need — Understanding the Transformer Model | by ...

The Journey of a Token: What Really Happens Inside a Transformer ...

CV中token、Patch Embedding、positional encoding的概念(多模态、ViT、Transformer)-CSDN博客

Explain the need for Positional Encoding in Transformer models (with ...

【深度学习】BERT详解 - 知乎

Understanding Transformer Self-Attention 💬 | Ryan Sereno

Google Colab

How LLMs Embeds Input Tokens? - by Nikita Prasad

Paper Note: Understanding Embeddings and Contextualized Representations ...

2. Data Preparation and Sampling | Tyan Blog

A Gentle Introduction to Positional Encoding in Transformer Models ...

Transformer World: LLM의 기본 구조 뜯어보기 | HyperAccel Tech Blog

How Far Apart Does a Model Think Its Tokens Are? - Brendan Long

Paper-Reading-Notes - Yevzh's Space