Why model size doesn't decrease after INT8 Quantization using pytorch ...
Kitchens4,222 ideas

Bathrooms2,442 ideas
Kids Rooms1,868 ideas
Bedrooms1,657 ideas
Powder Rooms1,638 ideas
Family Rooms1,414 ideas
Dining Rooms1,403 ideas
Laundry1,361 ideas
Basements1,338 ideas
Entries1,286 ideas
Home Bars1,168 ideas
Hallways1,131 ideas
Home Offices1,098 ideas
Living Rooms1,038 ideas
Nurseries923 ideas
Closets & Storage922 ideas
Sunrooms851 ideas
Decks792 ideas
“Quantization Int8 Model Size”
0 in catalog · +120 from web
More from the web

Elu int8 quantization doesn't reduce the size needed by the model on ...
INT8 Inference: 8-bit Quantization for AI Model Speed | Inference Systems

YOLOv5 Model INT8 Quantization based on OpenVINO™ 2022.1 POT API ...
INT8 quantization with same model and different weights · Issue #2705 ...
int8 model quantization · Issue #521 · traveller59/spconv · GitHub
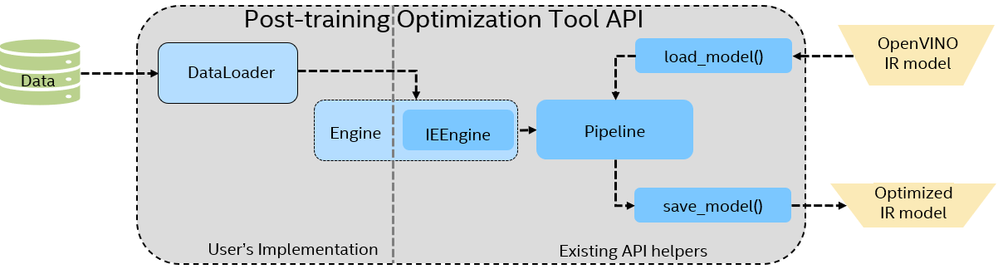
YOLOv5 Model INT8 Quantization based on OpenVINO™ 2022.1 POT API ...
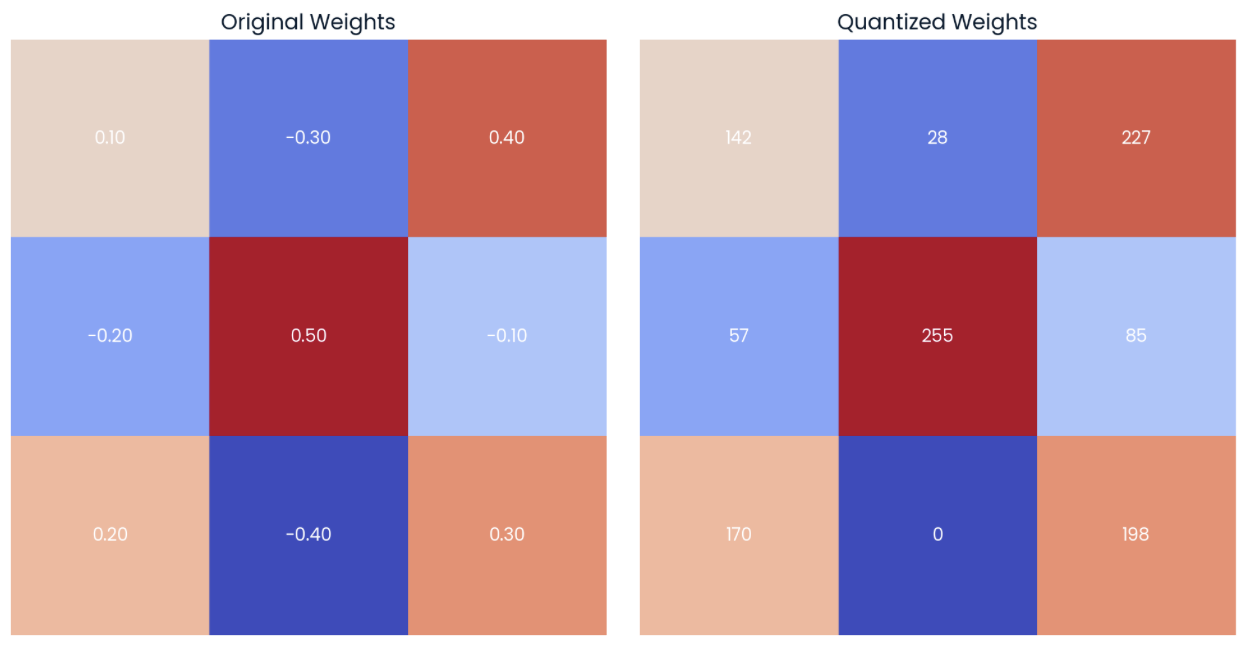
Quantization for Large Language Models (LLMs): Reduce AI Model Sizes ...

A Hands-On Walkthrough on Model Quantization - Medoid AI
INT8 Quantization: Definition & AI Model Optimization | Inference Systems

INT8 Quantization: Absmax, Smooth Quantization & Implementation ...
Quantization Methods for 100X Speedup in Large Language Model Inference
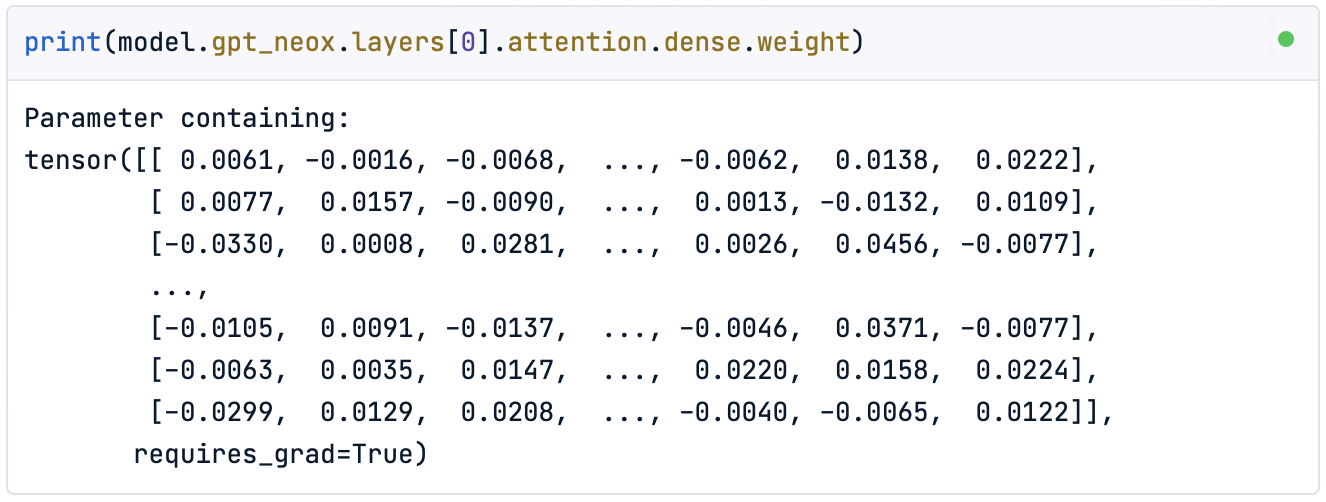
Quantization for Large Language Models (LLMs): Reduce AI Model Sizes ...

INT8 Quantization: Absmax, Smooth Quantization & Implementation ...
Overview of accuracy, quantization, inference time and model size of ...

Quantization for Large Language Models (LLMs): Reduce AI Model Sizes ...
Overview of accuracy, quantization, inference time and model size of ...

Quantization for Large Language Models (LLMs): Reduce AI Model Sizes ...

Quantization Aware Training with TensorFlow Model Optimization Toolkit ...
How to provide calibration data for INT8 quantization with dynamic ONNX ...

Improving LLM Inference Latency on CPUs with Model Quantization ...

INT8 Quantization: Absmax, Smooth Quantization & Implementation ...

The number of parameters and model sizes after encoder quantization for ...

Model Quantization
Effects of quantization on the CNN model accuracy. Quantization can ...
Model size after quantization, v.s. accuracy. To compare with ...

Deep Learning INT8 Quantization MATLAB Simulink, 42% OFF

Average model sizes with different quantization schemes | Download ...

INT8 Quantization for x86 CPU in PyTorch – PyTorch

INT8 Quantization | adamgallas/fpga_accelerator_yolov3tiny | DeepWiki
Int8 Quantized model same output on different inputs · Issue #23330 ...

Int8 quantization and tvm implementation - Programmer Sought

Introducing Post-Training Model Quantization Feature and Mechanics ...

Effects of Quantization on Accuracy and Model Size. | Download ...

NVIDIA TensorRT INT8 & FP8 quantization accelerating SD inference : r ...

Deep Learning INT8 Quantization - MATLAB & Simulink

Profiling, Quantization & Model Optimization

Model size after quantization, v.s. model accuracy. All layers are ...

Improving LLM Inference Latency on CPUs with Model Quantization ...

Overview of accuracy, quantization, inference time and model size of ...

Quantization of Neural Network Model for AI Hardware - Gyrus AI | Blog ...

Quantized model parameter after PTQ, INT8? - quantization - PyTorch Forums

Model Quantization Technologies with AIMET.pdf

神经网络参数量化,模型压缩论文笔记Training with Quantization Noise for Extreme Model ...

What is Model Optimization? A Quick Guide

Quantization: INT8 vs FP16 vs FP32 | MetricGate

Update #31: Expectations for AI + Healthcare and 8-bit Quantization

Unlocking LLM Performance: Advanced Quantization Techniques on Dell ...

Model Quantization: Run Large AI Models on Limited Hardware

Quantization in LLMS (Part 1): LLM.int8(), NF4 | TensorTunes

Quantization Overview — Guide to Core ML Tools

Quantization in LLMS (Part 1): LLM.int8(), NF4 | TensorTunes

Understanding The Impact Of Model Compression Techniques On Mobile App ...

Convert and quantize the model | Arm Learning Paths

Light Weight machine learning Model for embedded environmeents | PPTX

[2303.17951] FP8 versus INT8 for efficient deep learning inference

Quark Quantized INT8 Models - a amd Collection

Introduction to Quantization cooked in 🤗 with 💗🧑🍳

Introduction to Weight Quantization | Towards Data Science

Effective Weight-Only Quantization for Large Language Models with Intel ...

Local Large Language Models | Int8

The Ultimate Handbook for LLM Quantization | Towards Data Science

Quantization from FP32 to INT8. | Download Scientific Diagram

PyTorch Quantization - GeeksforGeeks

Quantization for Local LLMs: How It Works and Which Formats Fit Your Setup

(PDF) Understanding INT4 Quantization for Transformer Models: Latency ...

A Visual Guide to Quantization - Maarten Grootendorst

Model Memory Requirements Explained: How FP32, FP16, BF16, INT8, and ...

What is Quantization and how to use it with TensorFlow
GitHub - SRDdev/Model-Quantization: Quantization is a technique to ...

Beyond YOLOv8n: Quantization and Pruning for Efficient Obstacle ...

A Method of Deep Learning Model Optimization for Image Classification ...

Model compression and Mixture-of-Experts

딥러닝의 Quantization (양자화)와 Quantization Aware Training - gaussian37

Local Large Language Models | Int8

Quantization from FP32 to INT8. | Download Scientific Diagram
Quantization: Reducing Model Precision (FP16, INT8)

Introduction to Weight Quantization | Towards Data Science

Quantization from FP32 to INT8. | Download Scientific Diagram

Quantization | LLM-visuals

How to optimize large deep learning models using quantization

Understanding LLM.int8() Quantization — Picovoice

AI Model Optimization: Maximizing Performance and Efficiency | IT-Magic

HAWQ-V3: Dyadic Neural Network Quantization | PDF

BridgePhase » Insights

Custom SLMs & Edge Deployments Services

ch1

GPU memory requirements for serving Large Language Models | UnfoldAI

TensorRT的两种INT8量化方式: QTA, PTQ_tensorrt 量化工具-CSDN博客

[2305.12356] Integer or Floating Point? New Outlooks for Low-Bit ...

Serving Quantized LLMs on NVIDIA H100 Tensor Core GPUs | Databricks Blog

�Practical Approaches to DNN Quantization,” a Presentation from Magic ...

INT4, INT8, and When Accuracy Actually Drops | Luca Berton

QuantYOLOModels.pdf

ch1

Maximizing Business Potential with Large Language Models (LLMs)

GPU memory requirements for serving Large Language Models | UnfoldAI

50张图解密大模型量化技术:INT4、INT8、FP32、FP16、GPTQ、GGUF、BitNet_gptq量化-CSDN博客

Deep Learning Performance Characterization on GPUs for Various ...
GitHub - Armitawh/Edge-ML-Quantization-Benchmark: Hardware-aware ...

CPU-Optimized Embedding Models with fastRAG and Haystack | Haystack

利用TensorRT实现INT8量化感知训练QAT_tensorrt int8量化-CSDN博客

[2407.09111] Inference Optimization of Foundation Models on AI Accelerators

Deep Learning Performance Characterization on GPUs for Various ...

模型量化-llm量化 - 知乎

大模型量化技术原理:FP8_e4m3-CSDN博客

Ian Huang

大语言模型的模型量化(INT8/INT4)技术_int8和int4-CSDN博客

所谓INT8量化 - 知乎

Cost Optimization in LLM Hosting | AI Tutorial | Next Electronics

Deep Learning Performance Characterization on GPUs for Various ...

大模型入门指南 - Quantization:小白也能看懂的“模型量化”全解析-CSDN博客

大模型入门指南 - Quantization:小白也能看懂的“模型量化”全解析_大模型量化-CSDN博客

Running Llama 2 on CPU Inference Locally for Document Q&A | Towards ...

Efficient execution of quantized deep learning models a compiler ...

51OpenLab-一站式ICT创新服务平台

50张图解密大模型量化技术:INT4、INT8、FP32、FP16、GPTQ、GGUF、BitNet_gptq量化-CSDN博客

[2307.09782] ZeroQuant-FP: A Leap Forward in LLMs Post-Training W4A8 ...

LLM Quantization: Making models faster and smaller | MatterAI Blog

ONNX详解之七:onnx模型int8量化 - 知乎